The arrival of Configurable Hybrid Reasoning with Extended Thinking in Claude 3.7 Sonnet marks a milestone in mission-critical software engineering. For the first time, software architects possess programmatic runtime control via API over the precise balance between sub-second streaming inference and deep cognitive computation scaling across tens of thousands of hidden thinking tokens.
1. The Test-Time Compute Duality in Modern Architectures
Historically, enterprise engineers were locked into a restrictive trade-off: adopt lightweight models optimized for sub-second API roundtrips, or route complex tasks to high-latency reasoning engines incapable of responsive interactive streaming.
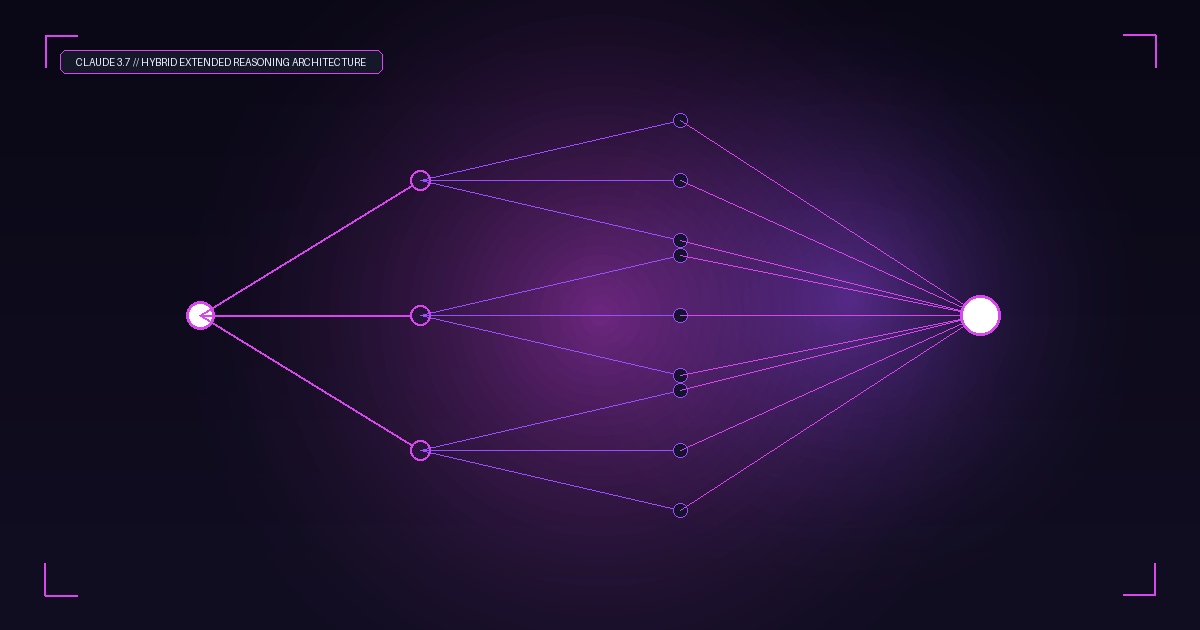
Claude 3.7 Sonnet resolves this friction by unifying both modalities within a single architecture. Utilizing the dynamic Thinking Budget parameter, developers can instruct the engine to respond instantly for deterministic transformations or allocate up to 64,000 internal reasoning tokens to untangle complex distributed race conditions, refactor massive codebases, or conduct multi-vector smart contract vulnerability audits.
Autonomous Code Synthesis Benchmark: Across rigorous industry benchmarks such as SWE-bench Verified, activating extended thinking boosts autonomous real-world issue resolution past 70%, proving the model's capacity to simulate internal memory states before emitting production code.
2. Anatomy of Hidden Cognitive Chains (Private CoT)
The tokens synthesized during extended thinking constitute a private, uncorrupted Chain-of-Thought (CoT) phase. During this execution window, the model:
- Formulates adversarial counter-hypotheses and stress-tests its own architectural assumptions.
- Simulates sequential control-flow branches and database concurrency states mentally.
- Catches edge-case logic regressions prior to publishing the user-facing response payload.
3. Engineering Resilient Software Pipelines at Better2Better
At Better2Better, we leverage hybrid reasoning within continuous verification workflows. Our specialized developer agents employ zero-budget instantaneous inference for schema linting and unit testing, dynamically triggering deep reasoning budgets whenever cryptographic edge cases or architectural anomalies arise.
4. Thinking Budget Allocation Matrix
| Engineering Use Case | Recommended Budget | System Characteristics |
|---|---|---|
| REST APIs & Interactive UI | Disabled / 0 tokens | Sub-second p95 latency, rapid streaming response. |
| Full-Stack Code Refactoring | 2,048 – 8,192 tokens | Strict typing, dependency graph resolution, integration tests. |
| Smart Contract & Crypto Audits | 16,384 – 32,768 tokens | Formal invariant checking, reentrancy analysis, liquidity math. |
| Distributed Systems Architecture | Up to 64,000 tokens | Fault-tolerant consensus analysis and partition recovery modeling. |
5. Technical References & Foundations
Official Publications & Foundational Papers:
- Anthropic Technical Report (2025). Claude 3.7 Sonnet and the Emergence of Dynamic Hybrid Reasoning. Anthropic Publications.
- Wei, J., Wang, X., Schuurmans, D., et al. (2022). Chain-of-Thought Prompting Elicits Reasoning in Large Language Models. NeurIPS 2022, arXiv:2201.11903.
- Snell, C., Lee, J., Xu, K., & Kumar, A. (2024). Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Parameters. arXiv:2408.03314.
Enterprise AI Security Guarantees & Cryptographic Code Audits
Deploying autonomous agent swarms without hardened defense layers is the single highest operational risk in modern computing. At Better2Better, our dedicated team led by Felipe Siqueira and Dr. Helena Vance performs deep architectural code audits, neutralizing prompt injections, securing vector memories in gVisor sandboxes, and orchestrating execution across encrypted hardware enclaves.
What can we build for you today?
Enjoyed this deep dive? Deploy enterprise autonomous AI agent swarms with guaranteed security hardening clicking here!
🤖 Deploy Autonomous AI Agents via WhatsAppEnterprise AI Security Guarantees & Cryptographic Code Audits
Deploying autonomous agent swarms without hardened defense layers is the single highest operational risk in modern computing. At Better2Better, our dedicated team led by Felipe Siqueira and Dr. Helena Vance performs deep architectural code audits, neutralizing prompt injections, securing vector memories in gVisor sandboxes, and orchestrating execution across encrypted hardware enclaves.
What can we build for you today?
Enjoyed this deep dive? Deploy enterprise autonomous AI agent swarms with guaranteed security hardening clicking here!
🤖 Deploy Autonomous AI Agents via WhatsApp